We use cookies, including third-party cookies from Google to serve personalized ads through AdSense, to operate this site and understand how it is used. By continuing to browse, you accept this use. See our Privacy Policy and Terms of Use for details, including how to opt out of personalized advertising.
Accept
SmartData CollectiveSmartData Collective
  • Analytics
    AnalyticsShow More
    chatgpt image jul 21, 2026, 04 34 30 pm
    4 Core Benefits of Predictive Maintenance after Vibration Analysis
    10 Min Read
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results -- AI-generated illustration
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results
    11 Min Read
    chatgpt image jul 13, 2026, 04 23 45 pm
    How Data Analytics Helps Companies Improve User Engagement
    19 Min Read
    chatgpt image jul 13, 2026, 03 59 46 pm
    How Data Analytics Improves Multi-Location Search Strategies
    10 Min Read
    cybersecurity efforts
    How Behavioral Analytics and AI Are Redefining Cybersecurity for Boca Raton Businesses
    14 Min Read
  • Big Data
  • BI
  • Exclusive
  • IT
  • Marketing
  • Software
Search
© 2008-25 SmartData Collective. All Rights Reserved.
Reading: Preparing Yourself to Move to Apache Spark
Share
Notification
Font ResizerAa
SmartData CollectiveSmartData Collective
Font ResizerAa
Search
  • About
  • Help
  • Privacy
Follow US
© 2008-23 SmartData Collective. All Rights Reserved.
SmartData Collective > Software > Hadoop > Preparing Yourself to Move to Apache Spark
Big DataData ManagementHadoopMapReduceUnstructured Data

Preparing Yourself to Move to Apache Spark

kingmesal
kingmesal
6 Min Read
Preparing Yourself to Move to Apache Spark
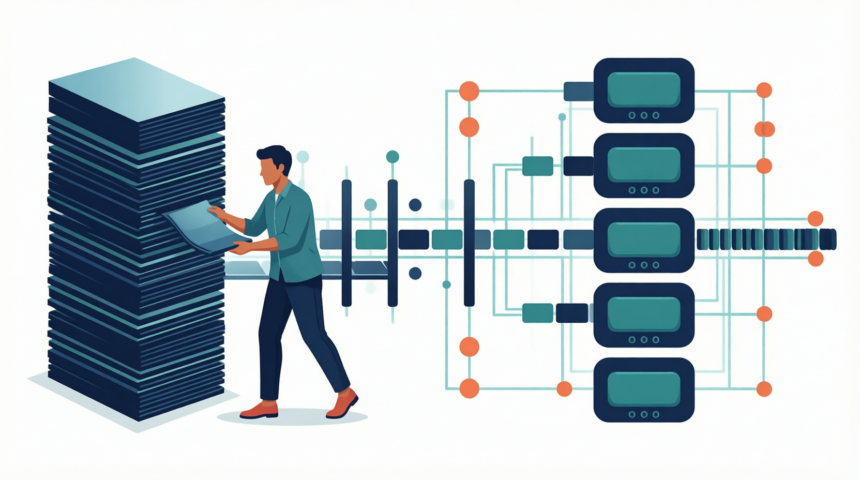
Illustration generated with Qwen Image.
SHARE

IT is an industry that’s always moving. While some things will never go out of style, like the Unix development model and knowing how to design algorithms properly, often you have to throw out what seems like a perfectly good tool or development style in search of something new.

Contents
  • Map and Reduce
  • Partitioning
  • Counters
  • Serialization
  • Conclusion

While MapReduce has been the mainstay of Hadoop processing, Apache Spark is now taking the throne as the way to handle distributed computation. The reasons are obvious: Spark is very fast due to its use of Resilient Distributed Datasets, or RDDs, and it has a clean programming model.

If you’ve been using the older MapReduce framework, you might wonder how much you need to learn before you can jump in and start using Spark. Fortunately, it’s easy to convert what you already know from MapReduce to Spark.

Map and Reduce

The biggest difference from MapReduce is how the Map and Reduce options are implemented.
More Read

Measuring Social Media ROI: Leveraging Data To Boost Results
Big Data and the Myth of Consumer Control
Are Data Scientists the Next Masters of the Universe?
The Growing Role of Analytics in Business Knowledge Management
Big Data Changes The Future Of The Data Recovery Industry

To understand this, you need to know how RDDs, Spark’s main data structure, work. RDDs allow for two kinds of operations on data: transformations and actions.

Transformationsare operations that change or filter operations in some way. Transformations are done nondestructively, keeping track of the original data. In a cluster, these changes can be spread out across different nodes. The master node keeps track of these different versions (called lineages) and can rebuild them on another node if one fails. It’s like having a giant RAID. An actionreturns some kind of result.

Given Hadoop’s history, one of the biggest transformations is map(), while reduce() is an action. As with their MapReduce counterparts, map() applies a function to a list, while reduce() aggregates data into a result. The big difference from MapReduce is that these operations are methods exposed by the RDDs themselves.

The programming model is much clearer under Spark than it is under MapReduce. MapReduce is written in Java, which, while not a bad programming language on its own, can be pretty bureaucratic in the way it makes you declare variables. Spark is written in Scala, a much cleaner functional language similar to Lisp or Haskell. 

A program to count lines might take about ten lines or so to write—but you can do it in a few lines of code in Spark with an example borrowed from the Apache Spark Cheat Sheet:

val word1=fm.map(word=>(word,1))
val wrdCnt=word1.reduceByKey(_+_)

What this does is create a variable with the word count in it. We’ve defined the word count by creating key-value pairs with all of the lines, with a value of one in the first line. The second line uses reduceByKey to add all of the keys together. The “_+_” is a placeholder variable meant to add all of the values by key. It’s worth remembering that in Spark, RDDs operate on strings rather than key/value pairs.

We could have squeezed all of this into one line:

val wrdCnt=lines.map(line => (line.length, 1)).reduceByKey(_ + _)

This shows that Spark operations can easily be chained together.

Partitioning

Even though Spark on its own is very fast, you’ll want to make sure that all of the jobs are partitioned well across all your nodes. RDDs can be repartitioned in a customer manner, including by key, or value or even hashing the values.

Counters

You can use counters to count items, such as the line example we showed you earlier. While this can be done using MapReduce, Spark exposes something called accumulators, which are much more powerful. In addition to integers, you can also count using floating point.

Serialization

Spark and MapReduce can translate parallel operations back into serial data structures. In both systems, it’s possible to customize how this happens. In Spark, you have a choice of systems, from the default Java implementation to the Kryo version. All you really have to do is set a variable in the Hadoop configuration file.

Conclusion

If this article has whetted your appetite, you might want to try exploring the Spark documentation resources that are available. When you’re ready for a more advanced playground, this is a great resource to get you started with Spark in your own Sandbox.

TAGGED:big data analytics
Share This Article
Facebook Pinterest LinkedIn
Share

Follow us on Facebook

Latest News

Flat editorial illustration: The article examines AI agents that escalate from legitimate data retrieval to attempted intrusions
OpenAI’s Government Website Incidents Raise a Hard Question for AI Agents: When Should They Stop?
Artificial Intelligence News Security
Flat editorial illustration: The article's core relationship is the alignment between customer behavioral data (visit frequency,
Data-Driven Loyalty: How Restaurants Use Behavioral Analytics to Optimize Revenue
Exclusive
Flat editorial illustration: The article's core relationship is that reliable eCommerce attribution depends on a unified, well-st
How eCommerce Data Teams Can Build Attribution That Holds Up
Big Data Exclusive
Flat editorial illustration: The article's core relationship is the contrast between fragmented inherited data infrastructure (wh
Data Stack Consolidation as a Data Quality and Governance Strategy for Mid-Market Teams
Big Data Exclusive

Stay Connected

1.2KFollowersLike
33.7KFollowersFollow
222FollowersPin

You Might also Like

How to Stay Ahead of the Data Protection Curve in 2016
Best PracticesBig DataData ManagementData QualityData Warehousing

How to Stay Ahead of the Data Protection Curve in 2016

5 Min Read
Fascinating Ways Machine Learning and Geolocation Tagging Are Intersecting
AnalyticsBig DataExclusiveFeaturedMachine LearningNews

Fascinating Ways Machine Learning and Geolocation Tagging Are Intersecting

6 Min Read
Envisioning Tourist Demand with Big Data
AnalyticsBig DataExclusive

Envisioning Tourist Demand with Big Data

4 Min Read
Splunk: Bringing Big Data Analysis to the Rest of Us
Data QualityData VisualizationHadoop

Splunk: Bringing Big Data Analysis to the Rest of Us

5 Min Read

SmartData Collective is one of the largest & trusted community covering technical content about Big Data, BI, Cloud, Analytics, Artificial Intelligence, IoT & more.

How To Get An Award Winning Giveaway Bot
Big Data Chatbots Exclusive
ai chatbot
How AI Website Chatbots Improve Customer Support and Lead Generation
Chatbots Exclusive

Quick Link

  • About
  • Contact
  • Privacy
Follow US
© 2008-26 SmartData Collective. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?