We use cookies, including third-party cookies from Google to serve personalized ads through AdSense, to operate this site and understand how it is used. By continuing to browse, you accept this use. See our Privacy Policy and Terms of Use for details, including how to opt out of personalized advertising.
Accept
SmartData CollectiveSmartData Collective
  • Analytics
    AnalyticsShow More
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers -- AI-generated illustration
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers
    7 Min Read
    chatgpt image jul 21, 2026, 04 34 30 pm
    4 Core Benefits of Predictive Maintenance after Vibration Analysis
    10 Min Read
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results -- AI-generated illustration
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results
    11 Min Read
    chatgpt image jul 13, 2026, 04 23 45 pm
    How Data Analytics Helps Companies Improve User Engagement
    19 Min Read
    chatgpt image jul 13, 2026, 03 59 46 pm
    How Data Analytics Improves Multi-Location Search Strategies
    10 Min Read
  • Big Data
  • BI
  • Exclusive
  • IT
  • Marketing
  • Software
Search
© 2008-25 SmartData Collective. All Rights Reserved.
Reading: Data Replication: The Reality
Share
Notification
Font ResizerAa
SmartData CollectiveSmartData Collective
Font ResizerAa
Search
  • About
  • Help
  • Privacy
Follow US
© 2008-23 SmartData Collective. All Rights Reserved.
SmartData Collective > Data Management > Best Practices > Data Replication: The Reality
Best PracticesBusiness IntelligenceData ManagementIT

Data Replication: The Reality

Erica Driver
Erica Driver
4 Min Read
Data Replication: The Reality
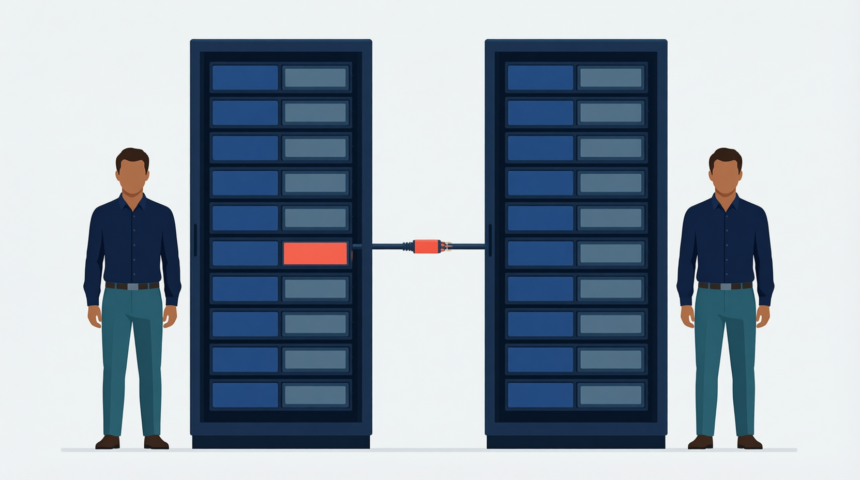
Illustration generated with Qwen Image.
SHARE

For a Business Discovery platform to meet the expectations of today’s information worker (fast response times, high degrees of interactivity, self-service data exploration and discovery) and scale across an enterprise, it’s now widely accepted that the use of in-memory processing is required.&

For a Business Discovery platform to meet the expectations of today’s information worker (fast response times, high degrees of interactivity, self-service data exploration and discovery) and scale across an enterprise, it’s now widely accepted that the use of in-memory processing is required.  Here’s a quote from our partner Teradata, which comes from a disk-based heritage: “Naturally for the data which is being used heavily on a day to day basis then there will a more than convincing business case to store this data in-memory to deliver the performance which is required by the business.”

This is no surprise to QlikTech, as this is the approach we pioneered 20 years ago, which is now being taken up by pretty much all competing vendors.

However, we sometimes come across claims that visualization tools querying direct to disk-based databases are a viable alternative approach.  To suggest that a deployment that only utilizes a dynamic query to disk approach will meet performance expectations is simply not a reality. While some business discovery providers (including QlikView via the Direct Discovery capability) can directly query sources such as Teradata, it’s important to acknowledge that direct query alone is a) much slower and b) utilizes network traffic in an unbounded fashion. Whilst a direct query capability such as Direct Discovery is a very valuable ‘relief valve’ for access to very large data sets, ALL data discovery providers (including QlikView) recommend the use of a performance optimization layer.  In fact, this is one of the defining characteristics of data discovery software according to Gartner (data discovery is their term for Business Discovery):

”Data discovery tools are an increasingly prominent class of BI offering that provide three attributes:

1. A proprietary data structure to store and model data gathered from disparate sources, which minimizes the reliance on predefined drill paths and dimensional hierarchies.

2. A built-in performance layer that obviates the need for aggregates, summaries or pre-calculations.

3. An intuitive interface enabling users to explore data without much training.”*

The reality is that any BI system meant to satisfy business users has to replicate some or all of the data to deliver acceptable performance. Different vendors take different approaches; QlikView uses its associative in-memory engine (which offers up to 90% compression of source data), other vendors use less intelligent in-memory caches, but all the same, they still replicate data. For 20 years QlikTech has developed an in-memory approach that provides a unique high-performance, associative, intelligent data store. In addition we have developed tooling that very effectively manages the data to allow QlikView deployments to scale to many thousands of concurrent users. Any vendor claiming to deliver genuinely useable, fast discovery without recourse to some data replication in memory (or the use of an in-memory database further down the stack – still a rarity) is misguided.  

*Source: Gartner ‘The Rise of Data Discovery Tools’, 26 September 2008, ID:G00161601

(Business discovery platform / shutterstock)
Share This Article
Facebook Pinterest LinkedIn
Share

Follow us on Facebook

Latest News

Flat editorial illustration: The article's core relationship is workload-by-workload decision-making for cloud migration, where s
Which Workloads Should Move to the Cloud?
Cloud Computing Exclusive IT
Flat editorial illustration: The article positions data governance as a strategic board-level concern rather than a purely techni
Why Data Governance Is Becoming a Board-Level Business Priority
Big Data Exclusive Policy and Governance
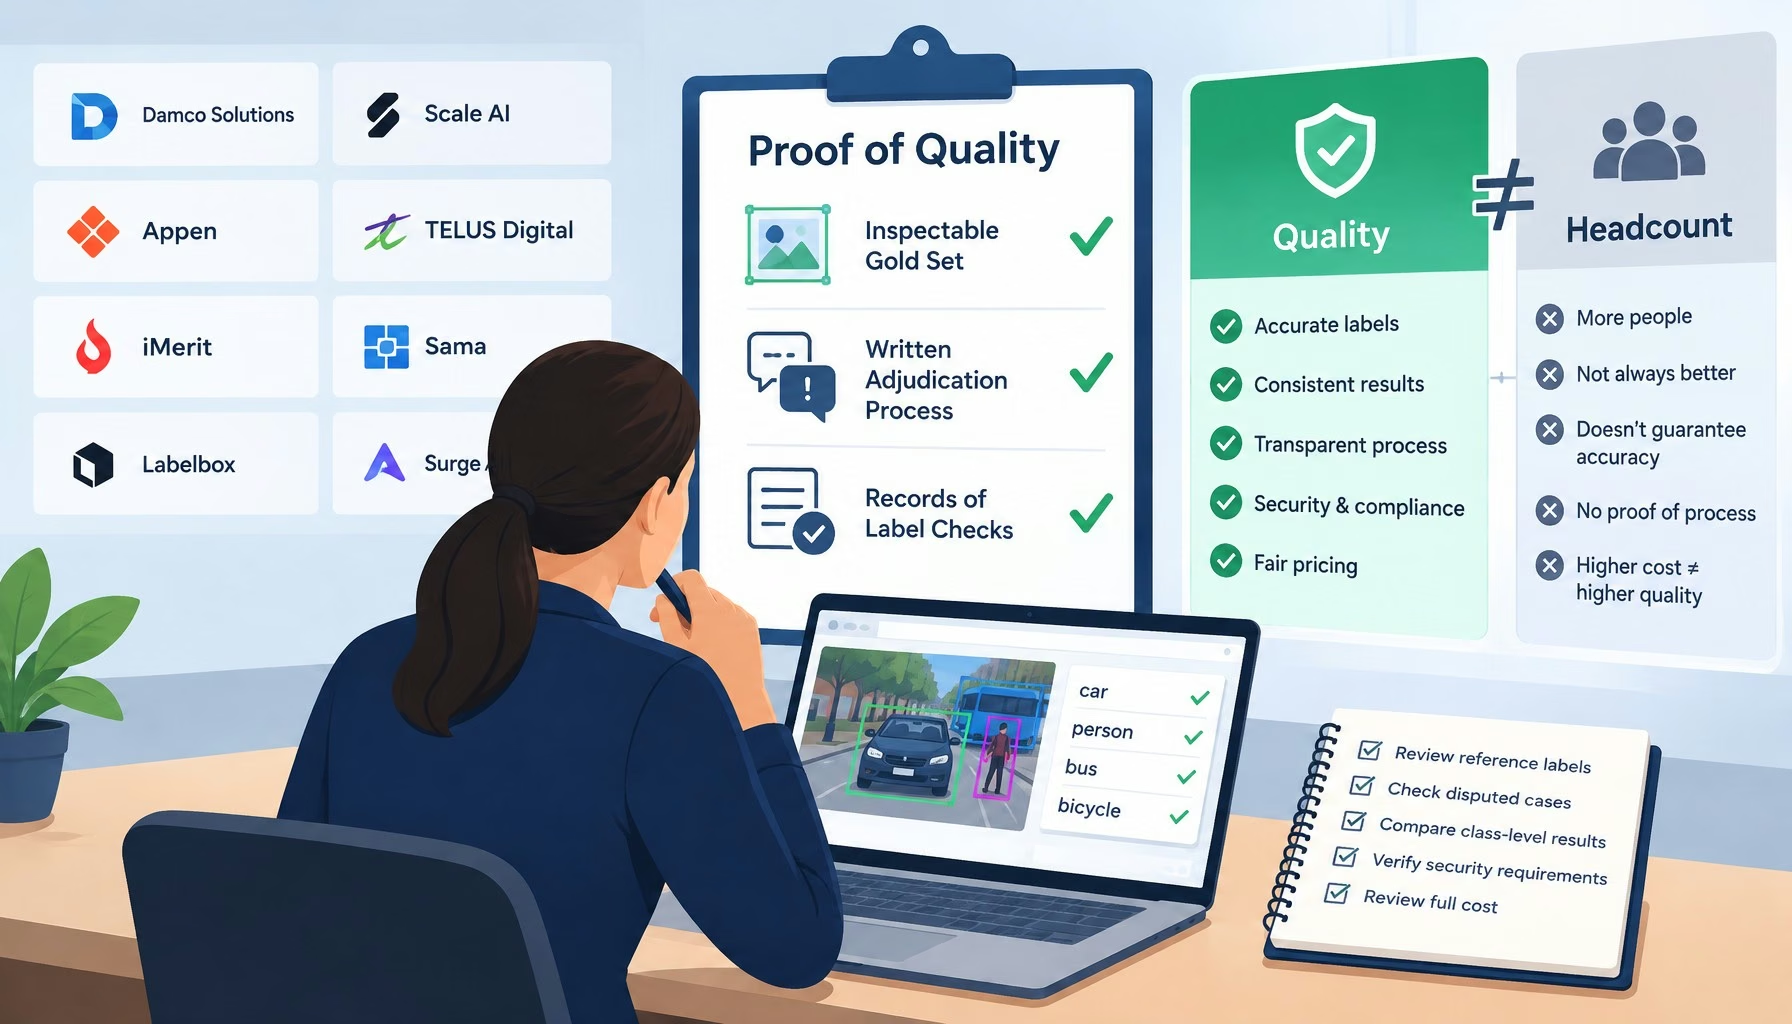
Flat editorial illustration: The article argues that data annotation quality should be measured by inspectable gold sets, written
The Top Data Annotation Companies Are Separated by Proof of Quality, Not Headcount
Big Data Exclusive
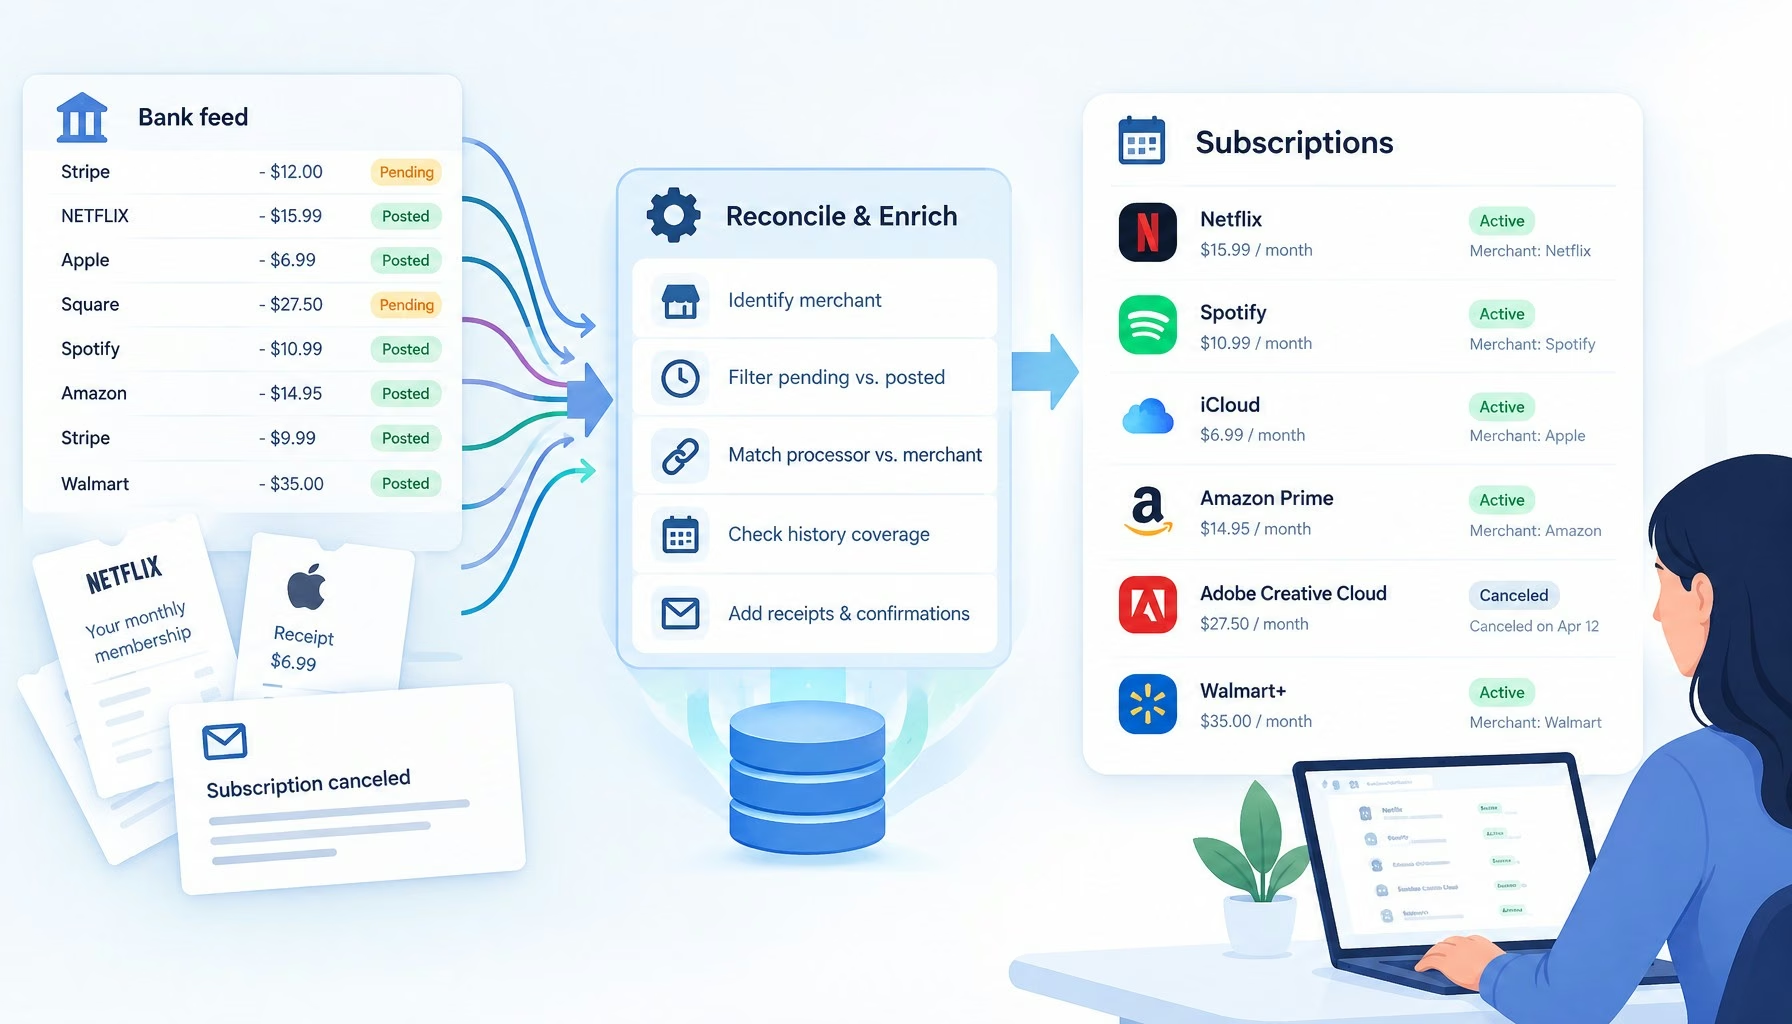
Flat editorial illustration: The article's core relationship is the gap between raw bank-feed records and reliable subscription i
Subscription Trackers Have a Transaction Data Problem
Big Data Exclusive

Stay Connected

1.2KFollowersLike
33.7KFollowersFollow
222FollowersPin

You Might also Like

multi model ai
Artificial IntelligenceExclusive

How Teams Using Multi-Model AI Reduced Risk Without Slowing Innovation

29 Min Read
agenic ai
Artificial IntelligenceExclusive

How Businesses Are Using AI to Make Smarter, Faster Decisions

The Twilight of Network-Centric Warfare
Business Intelligence

The Twilight of Network-Centric Warfare

8 Min Read
Online 'dating service' for tech jobs launched.
Best PracticesJobs

Online ‘dating service’ for tech jobs launched.

7 Min Read

SmartData Collective is one of the largest & trusted community covering technical content about Big Data, BI, Cloud, Analytics, Artificial Intelligence, IoT & more.

The Art of Conversation: Enhancing Chatbots with Advanced AI Prompts
Chatbots
Chatbots and SEO: How Can Chatbots Improve Your SEO Ranking?
Artificial Intelligence Chatbots Exclusive

Quick Link

  • About
  • Contact
  • Privacy
Follow US
© 2008-26 SmartData Collective. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?