We use cookies, including third-party cookies from Google to serve personalized ads through AdSense, to operate this site and understand how it is used. By continuing to browse, you accept this use. See our Privacy Policy and Terms of Use for details, including how to opt out of personalized advertising.
Accept
SmartData CollectiveSmartData Collective
  • Analytics
    AnalyticsShow More
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers -- AI-generated illustration
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers
    7 Min Read
    chatgpt image jul 21, 2026, 04 34 30 pm
    4 Core Benefits of Predictive Maintenance after Vibration Analysis
    10 Min Read
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results -- AI-generated illustration
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results
    11 Min Read
    chatgpt image jul 13, 2026, 04 23 45 pm
    How Data Analytics Helps Companies Improve User Engagement
    19 Min Read
    chatgpt image jul 13, 2026, 03 59 46 pm
    How Data Analytics Improves Multi-Location Search Strategies
    10 Min Read
  • Big Data
  • BI
  • Exclusive
  • IT
  • Marketing
  • Software
Search
© 2008-25 SmartData Collective. All Rights Reserved.
Reading: Precision and Recall
Share
Notification
Font ResizerAa
SmartData CollectiveSmartData Collective
Font ResizerAa
Search
  • About
  • Help
  • Privacy
Follow US
© 2008-23 SmartData Collective. All Rights Reserved.
SmartData Collective > Uncategorized > Precision and Recall
Uncategorized

Precision and Recall

Daniel Tunkelang
Daniel Tunkelang
5 Min Read
Precision and Recall
Illustration generated with Qwen Image.
SHARE

This month’s issue of IEEE Computer is a special issue featuring information seeking support systems, edited by Gary Marchionini and Ryen White. You can read their introduction for free here; unfortunately, the articles, while available online, are only free for IEEE Xplore subscribers.

What I can share is a 500-word sidebar I wrote that appears on p. 39, in an article by Peter Pirolli entitled “Powers of 10: Modeling Complex Information-Seeking Systems at Multiple Scales“.


Precision and Recall
More Read

Data Visualizations: The Tip of the Iceberg of Understanding
Adventures in MOOC: Back to School, Part 2
Things Interrupting the Internet of Things
Analytics at Work
Customer-Focused Marketing: Automation Is the Easy Part

Information retrieval (IR) research today emphasizes precision at the expense of recall. Precision is the number of relevant documents a search retrieves divided by the total number of documents retrieved, while recall is the number of relevant documents retrieved divided by the total number of existing relevant documents that should have been retrieved.

These measures were originally intended for set retrieval, but most current research assumes a ranked retrieval model, in which the search returns results in order of their estimated likelihood of relevance to a search query. Popular measures like mean average precision (MAP) and normalized discounted cumulative gain (NDCG) [1] mostly reflect precision for the highest-ranked results.

For the most difficult and valuable information-seeking problems, however, recall is at least as important as precision. In particular, for tasks that involve exploration or progressive elaboration of the user’s needs, a user’s progress depends on understanding the breadth and organization of available content related to those needs. Techniques designed for interactive retrieval, particularly those that support iterative query refinement, rely on communicating to the user the properties of large sets of documents and thus benefit from a retrieval approach with a high degree of recall [2].

The extreme case for the importance of recall is the problem of information availability, where the seeker faces uncertainty as to whether the information of interest is available at all. Instances of this problem include some of the highest-value information tasks, such as those facing national security and legal/patent professionals, who might spend hours or days searching to determine whether the desired information exists.

The IR community would do well to develop benchmarks for systems that consider recall at least as important as precision. Perhaps researchers should revive the set retrieval models and measures such as the F1 score, which is the harmonic mean of precision and recall.

Meanwhile, information scientists could use information availability problems as realistic tests for user studies of exploratory search systems, or interactive retrieval approaches in general. The effectiveness of such systems would be measured in terms of the correctness of the outcome (does the user correctly conclude whether the information of interest is available?); user confidence in the outcome, which admittedly may be hard to quantify; and efficiency—the user’s time or labor expenditure.

Precision will always be an important performance measure, particularly for tasks like known-item search and navigational search. For more challenging information-seeking tasks, however, recall is as or more important, and it is critical that the evaluation of information-seeking support systems take recall into account.

References

  1. K. Järvelin and J. Kekäläinen, “Cumulated Gain-Based Evaluation of IR Techniques,” ACM Trans. Information Systems, Oct. 2002, pp. 422-446.
  2. R. Rao et al., “Rich Interaction in the Digital Library,” Comm. ACM, Apr. 1995, pp. 29-39.

Link to original post

Share This Article
Facebook Pinterest LinkedIn
Share

Follow us on Facebook

Latest News

Flat editorial illustration: A tech-editorial depiction of contextual re-identification risk in linked unstructured support recor
Stripping the Names Isn’t Enough: De-Identifying Unstructured Data
Exclusive Unstructured Data
Flat editorial illustration: The article connects practical management of local data, memory and software environments with direc
How Data Professionals Optimize Devices for AI and ML Projects
Artificial Intelligence Data Science Exclusive Machine Learning
Flat editorial illustration: The article connects verified lease abstraction at signing to accurate property charges and faster m
AI Lease Abstraction and Month-End Close Speed-Up Checklist
Artificial Intelligence Exclusive
Flat editorial illustration: The article explains that file-system choice determines whether Windows, macOS, and Linux can read o
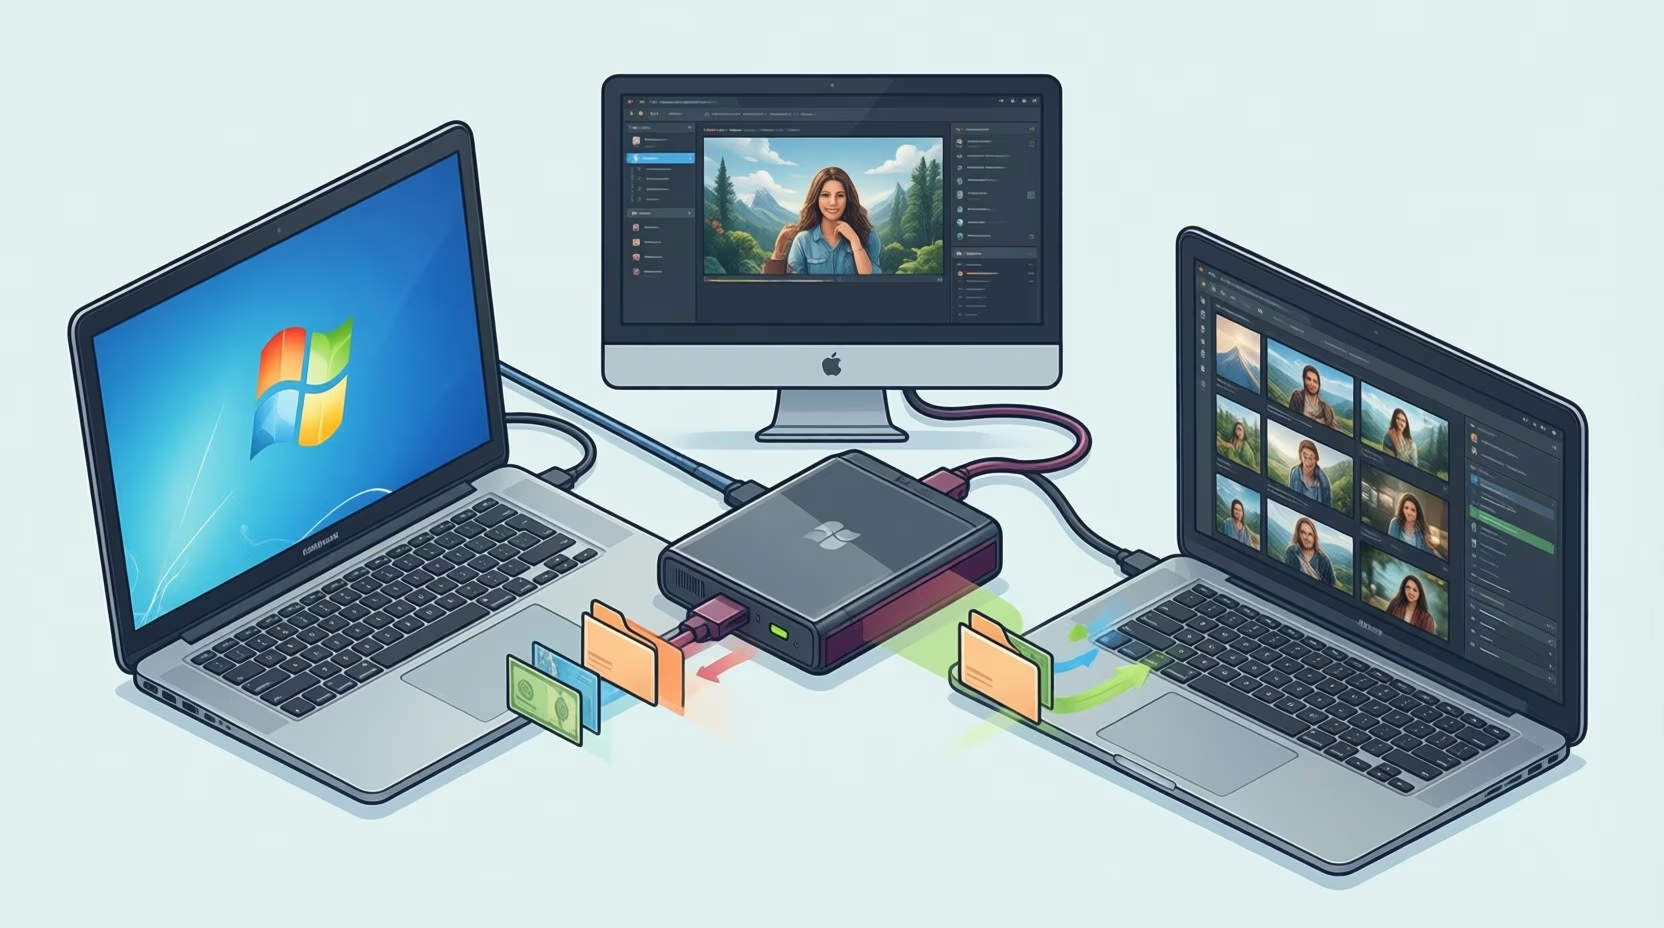
Understanding File System Compatibility Across Windows, macOS, and Linux
Cloud Computing Exclusive

Stay Connected

1.2KFollowersLike
33.7KFollowersFollow
222FollowersPin

You Might also Like

“TIME AND TIDE WAIT FOR NO MAN”
Uncategorized

“TIME AND TIDE WAIT FOR NO MAN”

6 Min Read
Change, Vested Interests, and Creative Destruction
Uncategorized

Change, Vested Interests, and Creative Destruction

6 Min Read
6 Ways to Futureproof Your Linux Infrastructure [SLIDESHARE]
Uncategorized

6 Ways to Futureproof Your Linux Infrastructure [SLIDESHARE]

3 Min Read
The Big Data Contrarians: New LinkedIn Big Data Community
Uncategorized

The Big Data Contrarians: New LinkedIn Big Data Community

6 Min Read

SmartData Collective is one of the largest & trusted community covering technical content about Big Data, BI, Cloud, Analytics, Artificial Intelligence, IoT & more.

The Art of Conversation: Enhancing Chatbots with Advanced AI Prompts
Chatbots
Chatbots and SEO: How Can Chatbots Improve Your SEO Ranking?
Artificial Intelligence Chatbots Exclusive

Quick Link

  • About
  • Contact
  • Privacy
Follow US
© 2008-26 SmartData Collective. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?