We use cookies, including third-party cookies from Google to serve personalized ads through AdSense, to operate this site and understand how it is used. By continuing to browse, you accept this use. See our Privacy Policy and Terms of Use for details, including how to opt out of personalized advertising.
Accept
SmartData CollectiveSmartData Collective
  • Analytics
    AnalyticsShow More
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers -- AI-generated illustration
    What Kind of Problem-Solving Distinguishes Data Analysts From Software Engineers
    7 Min Read
    chatgpt image jul 21, 2026, 04 34 30 pm
    4 Core Benefits of Predictive Maintenance after Vibration Analysis
    10 Min Read
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results -- AI-generated illustration
    How Does Data Mining Boost Customer Satisfaction in Logistics? Harnessing Analytics for Results
    11 Min Read
    chatgpt image jul 13, 2026, 04 23 45 pm
    How Data Analytics Helps Companies Improve User Engagement
    19 Min Read
    chatgpt image jul 13, 2026, 03 59 46 pm
    How Data Analytics Improves Multi-Location Search Strategies
    10 Min Read
  • Big Data
  • BI
  • Exclusive
  • IT
  • Marketing
  • Software
Search
© 2008-25 SmartData Collective. All Rights Reserved.
Reading: What is Hadoop?
Share
Notification
Font ResizerAa
SmartData CollectiveSmartData Collective
Font ResizerAa
Search
  • About
  • Help
  • Privacy
Follow US
© 2008-23 SmartData Collective. All Rights Reserved.
SmartData Collective > Big Data > Data Mining > What is Hadoop?
Business IntelligenceData MiningData WarehousingPredictive Analytics

What is Hadoop?

TonyBain
TonyBain
5 Min Read
What is Hadoop?
Illustration generated with Qwen Image.
SHARE

Image via CrunchBase

Ok so you are setting out to build the next Google and are considering using a Map/Reduce based data access strategy over traditional SQL.  Just as you need a database server to process SQL queries you also require the underlying infrastructure to manage your data and to execute your Map/Reduce routines.  Hadoop is one such system that is gaining acceptance, being co-developed and implemented for data analytics purposes at Yahoo and Facebook amongst others.

Hadoop is the system that allows unstructured data to be distributed across hundreds or thousands of machines forming shared nothing clusters, and the execution of Map/Reduce routines to run on the data in that cluster.  Hadoop has its own filesystem which replicates data to multiple nodes to ensure  if one node holding data goes down, there are at least 2 other nodes from which to retrieve that piece of information.  This protects the data availability from node failure, something which is critical when there are many nodes in a cluster (aka RAID at a server level).

So will Hadoop outperform a RDBMS?  Well unless you are dealing with very large volumes of unstructured data (hundreds of GB, TB’s or PB’s) and have large numbers of machines available you will likely find the performance of Hadoop running a Map/Reduce query much slower than a comparable SQL query on a relational database.  Hadoop uses a brute force access method whereas RDBMS’s have optimization methods for accessing data such as indexes and read-ahead.  The benefits really do only come into play when the positive of mass parallelism is achieved, or the data is unstructured to the point where no RDBMS optimizations can be applied to help the performance of queries.  Indeed benchmarks from the Hadoop site show performance significantly slower in straight line query performance when compared to a relational DB on small scale tests.

More Read
Two Step Cluster - Customer Segmentation in Telecom
Two Step Cluster – Customer Segmentation in Telecom
How Predictive Analytics Turns Banks into Fortune Tellers
Keeping Sales & Marketing Data in Order: What startups must learn from the enterprise.
Big Data Makes a Big Difference
The Apocalypse of Abundance: 5 Steps to End the Insanity of Information Overload
 
MySql 5.0.27 Hadoop-0.15.2
Data B-tree disk table (MyISAM) Text files (access_log)
Machine 1 2
Rows 5,914,669 5,914,669
Results 100 100
Time 4.43 sec 172.30 sec

But with all benchmarks everything has to be taken into consideration.  For example, if the data starts life in a text file in the file system (e.g. a log file) the cost associated with extracting that data from the text file and structuring it into a standard schema and loading it into the RDBMS has to be considered.  And if you have to do that for 1000 or 10,000 log files that may take minutes or hours or days to do (with Hadoop you still have to copy the files to its file system).  It may also be practically impossible to load such data into a RDBMS for some environments as data could be generated in such a volume that a load process into a RDBMS cannot keep up.  So while using Hadoop your query time may be slower (speed improves with more nodes in the cluster) but potentially your access time to the data may be improved. 

Also as there aren’t any mainstream RDBMS’s that scale to thousands of nodes, at some point the sheer mass of brute force processing power will outperform the optimized, but restricted on scale, relational access methods.

So while Hadoop and Map/Reduce are gaining more popularity it shouldn’t be considered a like for like alternative to a relational RDBMS for most applications.  It is a specialized tool with a specialized set of criteria that need to be fulfilled to achieve benefit over more traditional approaches.

Related articles by Zemanta
  • Yahoo Search Wants to Be More Like Google, Embraces Hadoop
  • Yahoo’s Supercomputing Initiative Running Hadoop

Link to original postInnovations in information management
Share This Article
Facebook Pinterest LinkedIn
Share

Follow us on Facebook

Latest News

Technical architecture diagram and decision framework for the trouble with ai that won’t leave a job unfinished
The Trouble With AI That Won’t Leave a Job Unfinished
Artificial Intelligence News
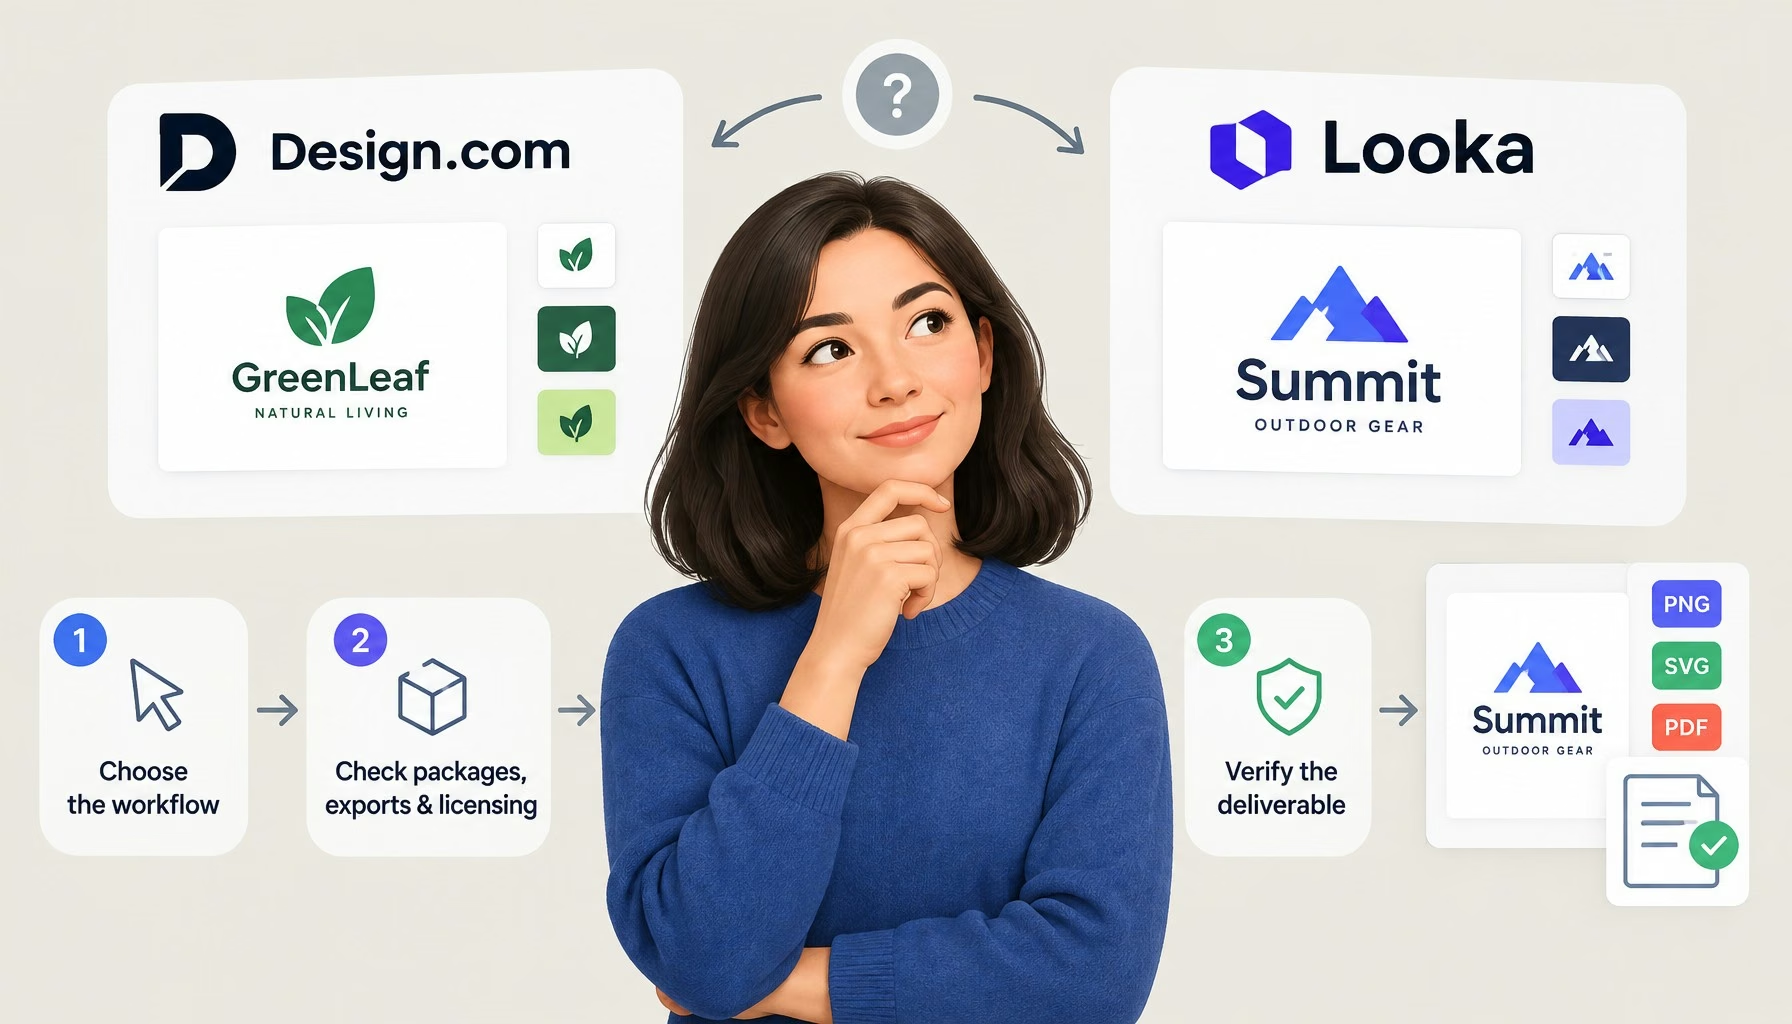
Technical architecture diagram and decision framework for ai-powered logo generation: design.com vs looka
AI-Powered Logo Generation: Design.com vs Looka
Artificial Intelligence Exclusive
Retailers Should Stop Treating Every Stockout as Equal -- AI-generated illustration
Retailers Should Stop Treating Every Stockout as Equal
Business Intelligence Exclusive
Best Vibe Coding Cleanup Specialists in the USA: Fix or Rebuild? -- AI-generated illustration
Best Vibe Coding Cleanup Specialists in the USA: Fix or Rebuild?
Development Exclusive

Stay Connected

1.2KFollowersLike
33.7KFollowersFollow
222FollowersPin

You Might also Like

8 Features of a True Enterprise-Grade Platform for Hadoop and NoSQL
AnalyticsBig DataBusiness IntelligenceCloud ComputingData QualityData VisualizationData WarehousingHadoopITMapReduceOpen SourceSocial DataSoftwareSQLUnstructured DataWorkforce Data

8 Features of a True Enterprise-Grade Platform for Hadoop and NoSQL

5 Min Read
Dashboard Design and Delivery Worst Practices
AnalyticsBest PracticesBusiness IntelligenceData Visualization

Dashboard Design and Delivery Worst Practices

18 Min Read
Interview: Karl Rexer - Rexer Analytics
Business IntelligenceData MiningPredictive Analytics

Interview: Karl Rexer – Rexer Analytics

18 Min Read
AI Is Reaching New Milestones In Senior Care In 2019
Artificial IntelligenceExclusive

AI Is Reaching New Milestones In Senior Care In 2019

5 Min Read

SmartData Collective is one of the largest & trusted community covering technical content about Big Data, BI, Cloud, Analytics, Artificial Intelligence, IoT & more.

How To Get An Award Winning Giveaway Bot
Big Data Chatbots Exclusive
Chatbots and SEO: How Can Chatbots Improve Your SEO Ranking?
Artificial Intelligence Chatbots Exclusive

Quick Link

  • About
  • Contact
  • Privacy
Follow US
© 2008-26 SmartData Collective. All Rights Reserved.
Welcome Back!

Sign in to your account

Username or Email Address
Password

Lost your password?